Understanding Jev: The Fast-Thinking "System 1" Model for AI
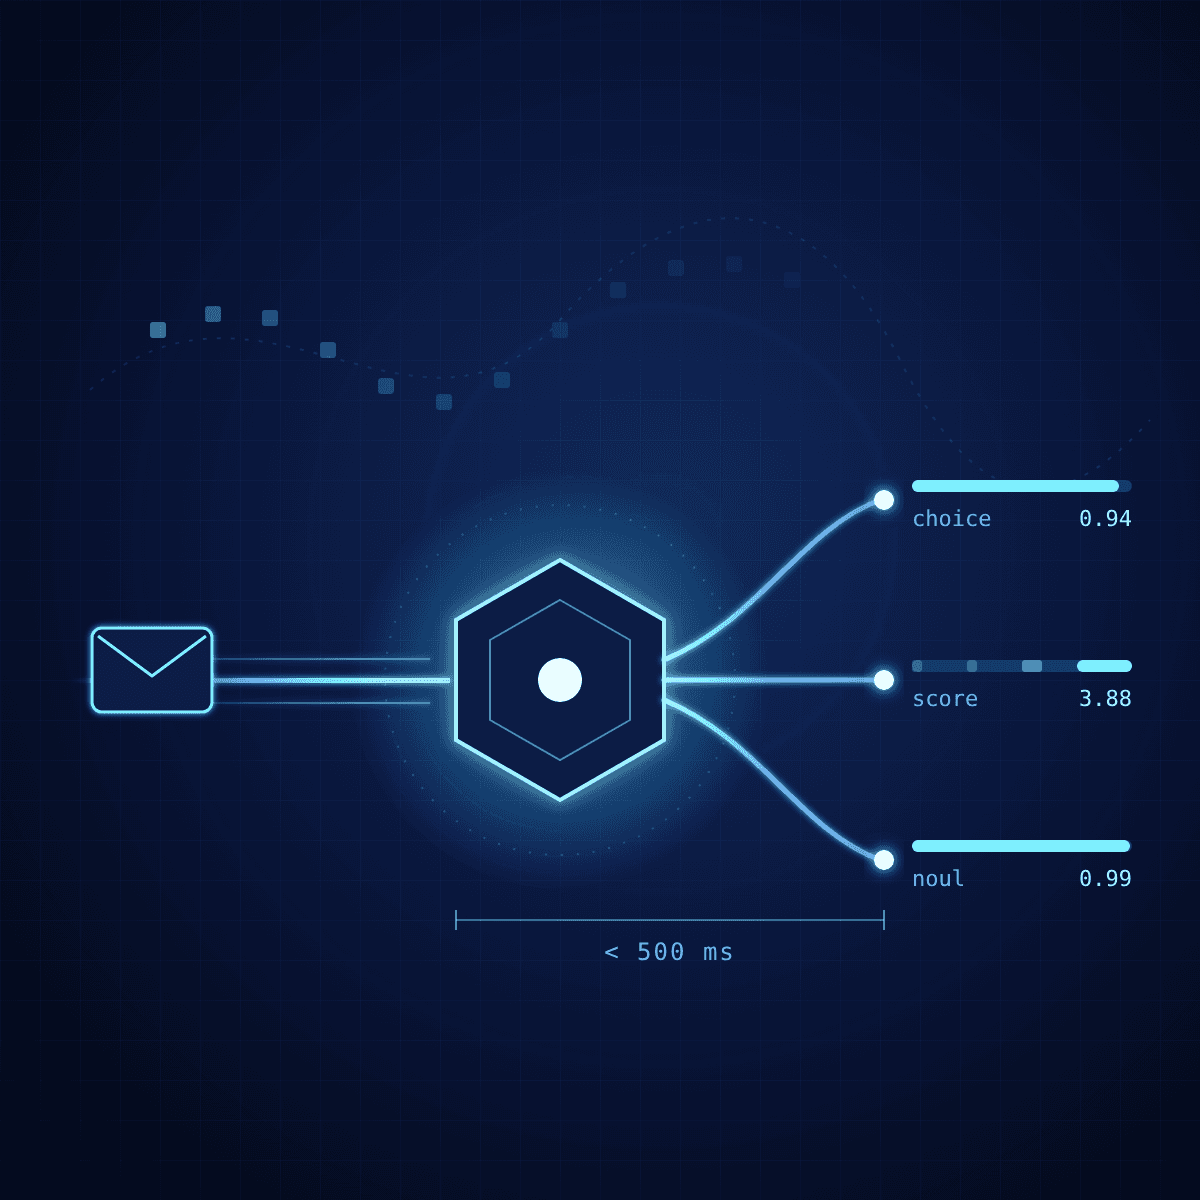
Think of large language models like GPT, Gemini, or Claude as specialist doctors who analyze your overall health and walk you through detailed diagnoses. In this system, Jev is the triage nurse at the front desk: it decides in seconds who goes where, so the specialists only see the cases that need them. Here’s why that matters for how we build software.
The Story Behind Jev
Jev comes from TypeSafe AI, a San Francisco startup co-founded by Diogo Almeida, one of the OpenAI researchers behind ChatGPT and the RLHF (Reinforcement Learning from Human Feedback) training that made it work. The company emerged from stealth on September 15, 2026, backed by a $40M seed round led by DCVC.
Unlike traditional chatbots, Jev isn't designed to hold conversations or compose lengthy text. Instead, you provide a contextual state and structured questions, and Jev returns clean, probability-scored results in less than half a second. TypeSafe AI refers to this as a "System 1" model, a brand-new class of AI purpose-built for ultra-fast, structured decisions inside software.
System 1 vs. System 2 Thinking
In his book Thinking, Fast and Slow, psychologist Daniel Kahneman described two distinct modes of human thought:
System 1 (Fast Thinking): Operates automatically and effortlessly. It manages routine decisions, instant reactions, and pattern recognition, like spotting a familiar sign or reacting to an unexpected obstacle.
System 2 (Slow Thinking): Requires deliberate focus and conscious effort. It handles complex logical reasoning, deep analysis, and calculations, like working through tax forms or writing code.
In modern AI architecture, standard LLMs act like System 2, handling deep reasoning and content creation. Jev acts like System 1, delivering instant, reliable decision-making at every decision point.
Three Ways to Build Decision-Making Software
Traditional Code: Relies entirely on hardcoded conditional rules. If an unforeseen scenario occurs, the system breaks or fails silently.
Full Agentic (LLM-Only): Routes every single decision through an LLM. While flexible, this approach is often slow, expensive, and difficult to predict reliably.
Hybrid Smart Software: Places a fast, low-cost decision model like Jev at every branch point, reserving heavy LLM processing strictly for steps that require dynamic text generation.
A Practical Example: Customer Support Triage
Consider an automated customer support triage pipeline designed to read incoming customer emails, assess urgency, route tickets to the correct department, and check whether a refund is requested.
Option A: The LLM-Only Approach
The Request: An incoming message is sent directly to a frontier LLM like GPT or Claude.
The Processing: To receive structured output, prompts must enforce strict JSON constraints. The LLM processes the input and generates text token-by-token.
The Bottleneck: The system waits for the full output to generate token by token, often several seconds with a frontier model, and you pay for every output token.
The Risk: Structured output modes now keep the JSON valid, but any confidence the model reports is just text it wrote, not a calibrated probability you can set thresholds on.
Option B: The Hybrid Architecture with Jev
The Request: The incoming message first goes to Jev as an initial System 1 triage filter.
The Processing: Jev evaluates urgency, department routing, and refund status in parallel in a single call, instead of generating text token by token.
The Speed: Structured results come back in 70 to 500 milliseconds, according to TypeSafe.
The Action: Because outputs always match the schema, code can act on the decisions right away. If Jev determines that a custom written response is needed, the request escalates smoothly to an LLM to generate the reply.
Comparing Concrete Output Examples
1. Traditional LLM Output (Generative Text/JSON)
Because standard LLMs rely on language generation, they produce conversational narrative text or construct formatted JSON strings piece by piece:
Drawbacks: Takes seconds to generate, consumes output tokens, and the confidence level is just a sentence the model wrote, not a calibrated probability.
2. Jev Output (Structured Primitives & Calibrated Probabilities)
Jev evaluates pre-defined decision types directly and outputs calibrated numerical probability distributions without extra conversational text (simplified here for readability; TypeSafe’s docs have the exact response format):
Benefits: Delivers schema-valid, calibrated outputs in well under a second at low cost, giving software systems instant, reliable signals for downstream routing.
Jev is in early access now through the TypeSafe API and OpenRouter. Pricing is $42 per billion input tokens, and output tokens are free.
Where We'd Use Jev for Clients
Most of the AI systems we build for clients have the same shape: a lot of small decisions wrapped around a few expensive ones. A text-to-SQL assistant first has to figure out which tables a question is even about. An insurance intake flow has to sort a claim by type and urgency before anyone reads it. A sales inbox needs every reply tagged as interested, not now, or unsubscribe. An agent has to pick the right tool before it calls anything. Right now most teams push all of that through an LLM and pay for it in latency and cost on every request.
That's the layer we'd hand to a model like Jev. The LLM keeps the work that needs real reasoning or a written answer, and the routing calls happen in milliseconds. Jev is still in early access, so we'd benchmark it against your current setup on your own data before switching anything over. If your AI bill or response times are getting out of hand, talk to us. We'll tell you straight whether a System 1 model would help or whether what you have is already fine.
Conclusion
Use Jev for the hundreds of small decisions your software makes every day, and use an LLM when you actually need it to write something. You get faster responses, predictable outputs, and a much smaller bill.